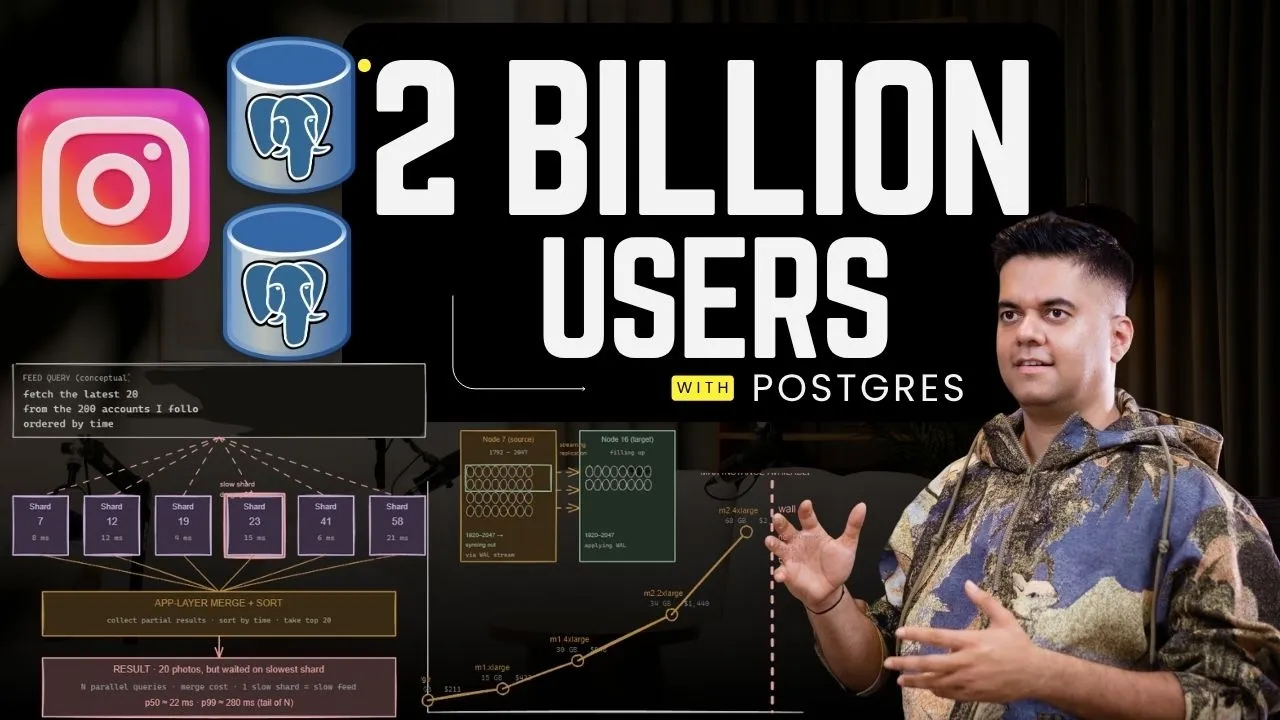
Akhil Sharma · 22:37 · Watch on YouTube
Summary
A visual case study of how Instagram scaled a single Postgres database — three engineers, EC2, S3 and one relational database in 2010 — into a sharded architecture that carried the product to planet scale, and why the team rejected the standard "move to NoSQL" advice along the way. The video walks the walls they hit in the order they hit them: connection memory exhaustion, the vertical scaling ceiling at 2 TB, the shard-key trade-off, and unique ID generation across thousands of independent shards. It then extracts the architectural patterns that outlived the specific implementation — decoupling logical shards from physical machines, Snowflake-style IDs implemented as a plain Postgres function — plus three underused Postgres features and an honest caveat about what Instagram actually runs today.
flowchart TD
    A["2010: one Postgres, 3 engineers"] --> B["Wall 1: connections eat RAM"]
    B -->|PgBouncer| C["Wall 2: vertical scaling ceiling, 2 TB"]
    C -->|Rejected: Cassandra / MongoDB| D["Decision: shard Postgres itself"]
    D --> E["Shard key = user ID<br/>fast single-user, expensive cross-user"]
    E --> F["Thousands of logical shards<br/>+ mutable mapping to physical nodes"]
    F --> G["Wall 3: auto-increment IDs collide"]
    G --> H["64-bit Snowflake-style IDs<br/>as a Postgres function"]
    H --> I["Lesson: boring tech + good engineering"]
Topics
- The premise: Postgres at planet scale
- The 2010–2012 architecture
- Bottleneck #1 — connections and PgBouncer
- The vertical scaling wall and the NoSQL decision
- Sharding by user — and the shard-key trade-off
- Logical vs physical shards — the mapping layer
- Snowflake-style IDs built into Postgres
- Boring technology as a superpower
- Three underused Postgres features
- What Instagram actually runs today
- The five rules and the closing argument
Key takeaways
- Instagram reached 27 million users on a 2 TB single Postgres database with only a few engineers before sharding — the ceiling was the biggest rentable EC2 instance's RAM plus saturated disk I/O, not Postgres itself (
0:58,1:33). - Connections, not data volume, were the first wall. At ~1.3 MB per connection, 50 app servers × 30 connections = 1,500 connections ≈ 2 GB of RAM burned before any query runs; PgBouncer collapsed that to ~30 real connections (
2:23,3:16). - They evaluated Cassandra and MongoDB seriously and still chose Postgres, on the reasoning that switching doesn't eliminate horizontal partitioning — it hides it behind another abstraction, and the migration is one-way (
4:32,4:51). - Sharding by user ID is a permanent trade: single-user queries hit one shard, but a 200-follow feed fans out to ~50 shards and merges in the application layer, where one slow shard slows the whole feed. Instagram accepted it and paid it back with caching, fanout and precomputed feeds (
7:33,8:01,8:21). - The central pattern: thousands of logical shards (Postgres schemas) mapped onto a changeable set of physical nodes — initially all on one machine. Rebalancing a node at 95% capacity means streaming-replicating half its logical shards to a new node and updating the mapping table; data, schemas and application code never change (
9:10,10:27,10:52). - Snowflake-style IDs were implemented as a Postgres function, not a service: 41 bits timestamp (41 years of ms), 13 bits shard ID (8,192 shards), 10 bits sequence (1,024 IDs/ms/shard ≈ 1M/sec). No coordination, no external dependency, no single point of failure — and
ORDER BY id DESCreplaces a timestamp index (13:47,14:16,14:44). - UUIDs were rejected for being large and unordered; Flickr-style ticket servers for being a single point of failure; Twitter's Snowflake for requiring a separate service to run and monitor (
12:27,13:22). - That ID pattern is now used by Discord, Slack and many large-scale applications (
15:21). - Three Postgres features carry real weight at scale: partial indexes (indexing only the last 30 days cuts 1B entries to 100M — 10× smaller and faster), functional indexes (indexing an 8-character prefix of 64-char tokens gives ~1/10 the index size with fast lookups), and logical replication (streams every insert/update/delete to search indexes, caches and warehouses — replacing hand-rolled Kafka and dual-write pipelines) (
18:17,19:08,19:36). - Caveat: this is history, not the current stack. The story covers 2010–2015; after the acquisition Meta absorbed Instagram into its own infrastructure, and the social graph is now served by TAO, Meta's distributed graph system (
20:06,20:33). - The diagnosis offered for the industry: the common mistake isn't picking the wrong database, it's switching too early, when the real fix was understanding the existing one better — "a lot of users" is not a new problem, unlike vector search, real-time time-series or planet-scale graph traversal (
16:13,16:45).