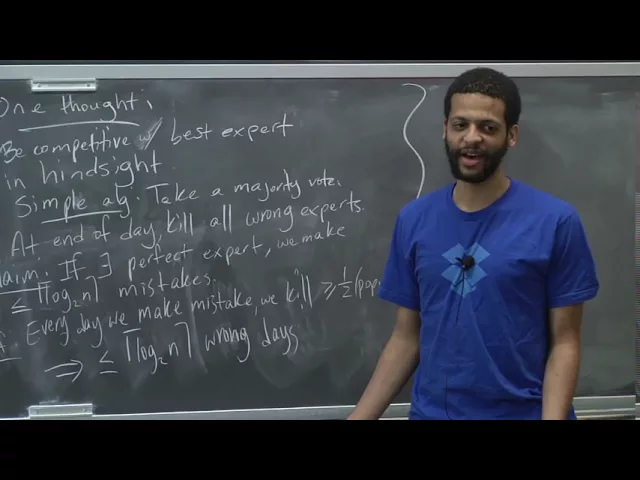
Harvard University · 1:21:33 · Watch on YouTube
Summary
This lecture introduces the multiplicative weights (MW) method, starting from the "listening to expert advice" problem: n experts give daily yes/no predictions and you must decide, aiming to make nearly as few mistakes as the best expert in hindsight. The lecture builds up through two warm-up algorithms (majority-vote-with-elimination, then with revival, giving a log n competitive ratio), then derives the weighted majority algorithm and its potential-function analysis, and finally generalizes to arbitrary cost vectors in [−1, 1]ⁿ with a probability distribution as output — yielding the standard MW regret bound. The last third pivots to applications: using MW to approximately solve linear programs, worked through on fractional set cover, with the key analogy that each LP constraint plays the role of an expert.
Type: university lecture (educational). Prerequisites referenced: competitive analysis, LP duality/relaxations, ellipsoid and interior point methods, randomized rounding for set cover.
flowchart TD
    A["Experts problem<br/>(§1)"] --> B["Majority vote + kill/revive<br/>≈ log n competitive (§2)"]
    B --> C["Weighted majority<br/>M ≤ 2(1+ε)·e + 2ln n/ε (§3)"]
    C --> D["Potential-function proof (§4)"]
    D --> E["General MW:<br/>distributions + costs in [−1,1]ⁿ (§5)"]
    E --> F["MW regret theorem + proof (§6)"]
    F --> G["Approximate LP feasibility (§7)"]
    G --> H["Fractional set cover (§8)"]
    G --> I["Constraints as experts (§9)"]
Topics
- Introduction and the "listening to expert advice" problem
- Majority vote, elimination, and revival
- The weighted majority algorithm
- Potential-function analysis of weighted majority
- Generalizing the model: distributions and real-valued costs
- Proof of the general MW theorem
- Using MW to approximately solve linear programs
- Worked example: fractional set cover
- The analogy: LP constraints as experts
Key takeaways
- A perfect expert makes plain majority-vote-with-elimination cheap: if some expert never errs, halving the population on every mistake bounds our mistakes by
log₂ n8:198:55. - Adding revival removes the perfection assumption at a log-factor cost: if the best expert makes
eerrors, the algorithm makes at most(e + 1)·log₂ nmistakes — at moste + 1phases, each costing at mostlog₂ n11:4613:33. - Weighted majority replaces the
log nmultiplicative factor with the constant 2:M(T) ≤ 2(1 + ε)·minᵢ mᵢ(T) + 2·ln n / εfor anyε ∈ (0, ½)— trading a multiplicative log for an additive term that was essentially already there16:2517:37. - The general MW regret bound: with
m(t) ∈ [−1, 1]ⁿand the updatepᵢ(t+1) ∝ (1 − ε)^{mᵢ(t)}·pᵢ(t), our expected cost satisfiesΣ_t ⟨m(t), p(t)⟩ ≤ Σ_t mᵢ(t) + ε·Σ_t |mᵢ(t)| + ln n / εfor every experti43:0749:23. - Both proofs are the same two-sided potential argument: upper-bound
Φ(t) = Σᵢ wᵢ(t)byn·e^{−ε·(our cost)}, lower-bound it by a single expert's weight, take logs26:5654:0654:50. - MW is fast but low-precision for LPs: its iteration count is
poly(1/ε)versus interior point'slog log(1/ε), and exact LP solving needsεexponentially small inL— so MW is only worth it when a(1 + ε)answer suffices1:07:591:08:14. - On fractional set cover, MW yields a
log n · (1 + ε)approximation quickly: binary-searchα ≥ OPT, run MW overP = {x ≥ 0, Σ x_S ≤ α}, rescale the(1 − ε)-violating output by1/(1 − ε)for cost(1 + O(ε))·α, then randomized-round1:14:171:15:29. - The LP-to-experts analogy hinges on an inverted sign: with
mᵢ = aᵢ·x − bᵢ, a large positive slack means the constraint is easy, so MW down-weights it and concentrates effort on the constraints still unsatisfied — exactly what approximate feasibility needs1:18:421:19:53.